---
language: "en"
---
# Lexogen's Online FAQs
## Featured FAQs
*
### [General Guidelines for Lexogen Kit Use](https://faqs.lexogen.com/faq/general-guidelines-for-lexogen-kit-use.md)
Before starting your RNA-Seq Experiment please read our General Guidelines for Lexogen Kit Use. You can consult our RNA LEXICON - a collection of RNA-Seq how-t...
*
### [Illumina Loading Guidelines for Lexogen libraries](https://faqs.lexogen.com/faq/illumina-loading-guidelines-for-lexogen-libraries.md)
Below you can find a table of advised loading concentrations for different Lexogen library pools on common Illumina sequencing platforms. If specified ranges a...
## FAQs by Product
*
### [General FAQs](https://faqs.lexogen.com/faq/general-product-and-technical-faqs.md)
This section gathers all general and technical Frequently Asked Questions (FAQs) related to Lexogen products.
*
### [Lexogen NGS Services](https://faqs.lexogen.com/faq/lexogen-ngs-services.md)
We have collected answers to the most important questions about our NGS services. If your needs are not or not completely addressed here, please contact our te...
*
### [QuantSeq](https://faqs.lexogen.com/faq/quantseq-3-mrna-seq-library-prep-kits.md)
The QuantSeq family product utilizes Lexogen's pioneering 3' mRNA-Seq approach, and is the ideal solution for Gene Expression Profiling. QuantSeq generates onl...
*
### [CORALL](https://faqs.lexogen.com/faq/corall-rna-seq-library-prep-kits.md)
The CORALL Total RNA-Seq Library Prep Kit V2 enables fast and cost-efficient generation of UMI labelled, stranded libraries for whole transcriptome analyses us...
*
### [LUTHOR High Definition](https://faqs.lexogen.com/faq/luthor-high-definition.md)
The LUTHOR High-Definition Single-Cell 3′ mRNA-Seq family products combine a novel direct RNA amplification technology with a 3' mRNA-Seq library preparation m...
*
### [Small RNA-Seq Library Prep Kit](https://faqs.lexogen.com/faq/small-rna-seq-library-prep-kit.md)
The Small RNA-Seq Library Prep Kit provides a protocol for generating small RNA libraries for Illumina sequencing directly from total RNA or enriched small RNA...
*
### [miRVEL](https://faqs.lexogen.com/faq/mirvel-small-rna-seq.md)
The Lexogen´s miRVEL sRNA-Seq Library Prep Kits utilize cutting-edge technology to generate small RNA-Seq libraries for Illumina Sequencing. The miRVEL Product...
*
### [SLAMseq](https://faqs.lexogen.com/faq/slamseq-metabolic-rna-labeling-kits.md)
The SLAMseq method: Thiol (SH)-Linked Alkylation for the Metabolic sequencing of RNA, enables the identification and quantification of newly synthesized (nasce...
*
### [Data Analysis](https://faqs.lexogen.com/faq/data-analysis-solutions.md)
Lexogen offers different solutions for NGS RNA-Seq Data Analysis. Please visit our bioinformatic webpage for more information about our data analysis solutions...
*
### [12 nt Unique Dual Indexing](https://faqs.lexogen.com/faq/indexing-solutions.md)
Lexogen's 384 12 nt Unique Dual Indices (UDIs) are available as pre-mixed i7/i5 combinations, in sets of 96, or 384. These can be purchased as: Add-on Kits con...
*
### [RiboCop](https://faqs.lexogen.com/faq/ribocop-rrna-depletion-kits.md)
RiboCop rRNA Depletion Kits for Human/Mouse/Rat, Bacteria, Yeast, Plant, and Fish enable efficient removal of ribosomal RNAs from total RNA and are suited for ...
*
### [Poly(A) Selection](https://faqs.lexogen.com/faq/poly-a-rna-selection-kit.md)
The Poly(A) RNA Selection Kit enables the rapid and highly specific enrichment of polyadenylated RNAs from total RNA samples. Visit our product page. Download ...
*
### [SPLIT](https://faqs.lexogen.com/faq/split-rna-extraction-kits.md)
SPLIT RNA Extraction Kit products enable fast and efficient extraction of high-quality RNA of all sizes, including small RNAs. Jump to FAQs for each Kit: SPLIT...
*
### [TraPR](https://faqs.lexogen.com/faq/trapr-small-rna-isolation-kit.md)
The TraPR Small RNA Isolation Kit is a gel- and bias-free, column-based method for the isolation of functional small RNAs from RNA-induced silencing complexes ...
*
### [RNA/DNA Defender](https://faqs.lexogen.com/faq/rna-dna-defender-solution.md)
The RNA/DNA Defender Solution allows for temporary storage of fresh tissue or cell samples without risking degradation of nucleic acids. Visit the RNA/DNA Defe...
*
### [TeloPrime](https://faqs.lexogen.com/faq/teloprime-full-length-cdna-amplification-kit.md)
The TeloPrime Full-Length cDNA Amplification Kit V2 is a 5' cap-specific protocol for generating full-length cDNA from total RNA. TeloPrime cDNA is compatible ...
*
### [SIRVs](https://faqs.lexogen.com/faq/spike-in-rna-variant-controls-sirvs.md)
Lexogen's Spike-In RNA Variant Controls (SIRVs) are synthetic, unique RNA transcripts, spanning a size range of 191 bp - 12 kb, which serve as controls for RNA...
*
### [Modules and Add-on Kits](https://faqs.lexogen.com/faq/modules-and-add-on-kits.md)
This section gathers Frequently Asked Questions (FAQs) related to Lexogen Modules and Add-on Kits. The table below lists the available Add-on Modules and Kits ...
---
language: "en"
---
# Products labeling
Lexogen has introduced an updated product label design that provides more information about your Lexogen products. Here you can find a quick guide to the new labels you can expect to see.
There are two common label formats:
## 1. Labels with User Guide Numbers and Download Links
These labels are found on products that have a Digital-only version of the User Guide available from the respective product page at: .

A new Lexogen Product Label with User Guide Number and Link.
## 2. Labels Without User Guide Numbers and Download Links
These labels are found on products that are still provided with printed User Guides (shipped together with the kit), or on modular kit components that do not have their own dedicated User Guide.

A new Lexogen Product Label without a User Guide Number and Link.
## Symbol Key
**REF:** The Article, or Product Part Number (e.g., **M16924**-2-0100) - a unique identifier for each manufactured product or module.
Many of our catalog products are modular and consist of one or more "parts".
**NOTE:**The first half of the Part Number (e.g., M16924) is unique to each product / module and can be provided to [sales@lexogen.com](mailto:sales@lexogen.com) if you have any questions about the products you receive.
**LOT:**The Lot Number - a unique identifier of a certain quantity of product produced in a single manufacturing run.
**BATCH:** The Batch number - a unique identifier of a defined combination of Lot Numbers.
**NOTE:**Please quote the **LOT and BATCH** Numbers when contacting tech support via [support@lexogen.com](mailto:support@lexogen.com) regarding any product-related questions or complaints.
**SIZE:** The number of reactions or preps that can be processed using the provided reagent volumes.

The recommended **storage temperature** range required for kit stability.

The **Product Expiry Date**: Performance cannot be guaranteed if the product(s) are used after this date.
The **User Guide Number** : e.g., **171UG394V0100**, defines the specific protocol to be used with the provided products. This number can be found on the bottom left hand corner of all of[Lexogen's User Guides](https://www.lexogen.com/docs).
The URL below the User Guide Number tells you where to download it from the Lexogen Website.
---
language: "en"
---
# A lot of my reads are not mapped (reads too short). Is there anything I can do to map shorter reads?
The term "too short" in the "% of reads unmapped" category of "UNMAPPED READS" from the "starLog.final.out" file refers to the alignment length, not the read length. The average trimmed length before mapping is reported as "average input length". Significant "% of reads unmapped: too short" could either happen for normal-length reads that are not mapping well, or for reads that were too short (over-trimmed) before mapping. Therefore, check the following:
* Per Sequence GC content: check to see if there are any prominent peaks. If so, this could be an indication of contamination in the library.
* Overrepresented sequences: Check the origin of the top sequences by copying the sequence and pasting into BLASTn. If the sequences do not align to the species used for library preparation, there may be a contamination issue. A common cell culture contaminant is Mycoplasma.
* RNA-seq library preparation: ensure appropriate QC is performed on final libraries.
* Processing data errors: ensure the appropriate species was selected.
For additional support, contact [support@lexogen.com](mailto:support@lexogen.com).
---
language: "en"
---
# Why do I observe some ribosomal peaks after poly(A) selection?
Agilent's Bioanalyzer and other electrophoresis platforms often try to detect 18S and 28S rRNA peaks at all costs. Therefore, highly abundant transcripts are sometimes wrongly identified as rRNA.
In the traces below you will see that the Bioanalyzer software classifies two peaks within the trace of a poly(A)-selected sample as 18S and 28S rRNA (top figure). However, the overlay with diluted total RNA clearly demonstrates that those peaks are not rRNA peaks (bottom figure). Poly(A) selection was successful and no rRNA was left. This was also confirmed by RNA-Seq.

Figure 1 \| Bioanalyzer trace after the Poly(A) RNA Selection Kit was used with 5 µg of Universal Human Reference RNA (UHRR). The Bioanalyzer software wrongly classifies two peaks within the trace of the poly(A)-selected sample as 18S and 28S rRNA.

Figure 2 \| Overlay of Bioanalyzer traces before and after the Poly(A) RNA Selection Kit was used. The overlay with diluted total RNA clearly demonstrates that those peaks identified as rRNA (top figure) are not rRNA peaks. Red trace: diluted total Universal Human Reference RNA (UHRR), intact (RIN 8.5). Blue trace: poly(A)-selected RNA.
---
language: "en"
---
# All about Samples: requirements, preparation, submission and shipment
Information related to samples submitted for service projects.
---
language: "en"
---
# Are my libraries overcycled? If so, what should I do?
## How do look like overcycled libraries?
A second peak between 1,000 -- 9,000 bp, or an elevated baseline on a bioanalyzer trace that extends underneath the upper marker is an indication of overcycling (see Figure). Similar features can be seen with other types of microcapillary electrophoresis traces.

Figure \| Correct versus overcycled QuantSeq Library Results: Correctly cycled (10ng UHRR, 19 cycles, blue), overcycled (10ng UHRR, 24 cycles, red). Low input protocol modifications were used (skipping step 2, 1 hour incubation at 42 degrees C at step 4, reduced volumes of PB and PS at steps 16 and 29).
## What causes overcycling?
Overcycling occurs when too many PCR cycles are used for the final library amplification. In this case, the PCR reaction runs out of primers and template and generated ds-cDNA starts to denature and reanneal improperly. This results in longer bulky molecules that migrate at a lower speed on the Bioanalyzer chip or gels. This can interfere with exact library quantification for pooling and loading for sequencing if relying solely on the Bioanalyzer results.
## How can I quantify overcycled libraries?
A qPCR assay ([PCR Add-on kit, Cat. No. 208](https://www.lexogen.com/store/pcr-add-on-and-reamp-v2/)) for exact library quantification should be used in addition to Bioanalyzer or similar analyses, if such a high molecular weight peaks occurs and/or overcycling is suspected.
## What is the effect of overcycling on my data?
Overcycled libraries can still be sequenced. However, these may have more PCR duplicates, which can affect quantification accuracy and sample clustering (i.e., by PCA). Overcycling may lead to a distortion in gene expression quantification and hence should be avoided where possible.
## Should I sequence overcycled libraries or re-prep them?
In order to avoid possible biases in expression data, the best option would be to re-prep the libraries and use a lower number of PCR cycles for the library amplification. If the libraries cannot be re-prepped (i.e., due to precious or irreplaceable samples) it is best to proceed with sequencing.
## How can I prevent overcycling?
Perform the [qPCR assay](https://faqs.lexogen.com/faq/how-do-i-calculate-endpoint-cycle-numbers.md) to determine the optimal number of PCR cycles required for library generation.
For similar samples reduce the number of PCR cycles for library amplification (Endpoint PCR) to prevent over-cycling.
You can estimate the number of cycles to reduce according to the yield of overcycled libraries. To achieve half the yield, subtract 1 PCR cycle. To achieve 4x less yield, use 2 fewer cycles. To achieve 10x less yield, use 3 fewer PCR cycles.
---
language: "en"
---
# Are the data comparable between QuantSeq REV V1 and V2?
Our QuantSeq REV V2 is superior in several ways due to the updates made to kit components. The V2 of the kit detects more genes, generates higher yields, and longer libraries.
For information on the changes made between V1 and V2, please visit the following FAQ: [What are the updates to QuantSeq REV V2?](https://faqs.lexogen.com/faq/what-are-the-updates-to-quantseq-rev-v2.md)
---
language: "en"
---
# Are the data obtained with QuantSeq with UDI V1 and V2 comparable?
**Yes.**
We observe a high correlation between data obtained with the QuantSeq 3' mRNA-Seq V2 Library Prep Kit FWD with Unique Dual Indices (12nt) and the QuantSeq 3' mRNA-Seq Library Prep Kit FWD with Unique Dual Indices (V1).

Figure \| Correlation plot obtained with 500ng of UHR + SIRV3 control Set, comparing QuantSeq UDI "V1" (x axis) and the new "V2" (y axis).
---
language: "en"
---
# Are the long SIRVs (Set 4) also isoforms of a given gene?
The 15 long SIRV transcripts in SIRV-Set 4 each have a unique sequence to clearly separate the length feature from the isoform complexity feature.
---
language: "en"
---
# Are the reagents interchangeable between miRVEL Discovery and Profiling?
**No.**
Library prep reagents, PCR components and UDIs are **NOT** interchangeable between miRVEL Discovery and miRVEL Profiling.
---
language: "en"
---
# Are the UDI V2 Add-on kits compatible with libraries of other vendors?
The Lexogen UDI 12 nt Unique Dual Indexing V2 Add-on Kits are in theory compatible with all non-Lexogen library prep kits utilizing TruSeq™ -- compatible stubby adapters (P5 and P7 adapters).
P5 and P7 can be either ligated to the cDNA insert or also introduced by PCR, depending on the manufacturer's protocol.
Our UDI will be subsequently added by PCR (with the amplification mix provided in the Lexogen UDI Add-on V2 kit) on existing P5 and P7 stubby sequences.
Please contact [support@lexogen.com](mailto:support@lexogen.com) for more information, or in case you have any doubts about potential compatibility issues between your library generation kit and our UDI Add-on module.
---
language: "en"
---
# Are there any sample types that are not compatible with the RNA/DNA Defender Solution?
Due to the waxy coating on leaves, some plant tissues may require prior disruption to allow RNA/DNA Defender Solution to permeabilize. Additionally, very fatty tissue samples may be problematic.
---
language: "en"
---
# Are there recommendations for low RNA input?
RNA input amounts lower than 100 ng (for total RNA or enriched small RNA) require protocol adjustments. These adjustments include dilution of the 3' Adapter (A3), 5' Adapter (A5) and Reverse Transcription Primer (RTP) and adjusted endpoint PCR cycle numbers (see Appendix B of the [User Guide](https://www.lexogen.com/docs/small-rna/)).
The minimum amount of total RNA input depends on the small RNA content of the sample in question.
For samples with a small RNA content of 10 %, 1 ng total RNA may be used as the minimum input.
Increase the input material for total RNA samples with lower small RNA content.
---
language: "en"
---
# Are there recommendations for low RNA input and serum/plasma samples?
Total RNA input amounts lower than 100 ng, small RNA-enriched samples, and serum/plasma samples may require protocol adjustments. These adjustments include dilution of the 3' Adapter (A3), 5' Adapter (A5) and Reverse Transcription Primer (RTP) and adjusted endpoint PCR cycle numbers. Please see Appendix B of the [User Guide](https://www.lexogen.com/docs/mirvel-small-rna/).
The minimum amount of total RNA input depends on the small RNA content of the sample in question.
Increase the input material for total RNA samples with lower small RNA content.
---
language: "en"
---
# Are there some additional instructions for how to run the HPLC analysis for the S4U Incorporation assay (e.g. Column, temperature, injection volume, and flow rate)?
The samples should be run on a C18 column. In principle any C18 column could be used instead of the Supelco Discovery C18 reverse phase column (size 250 x 46 mm, particle size 5 mM), as indicated in the SLAMseq Explorer and Kinetics Kits [User Guide](https://www.lexogen.com/docs/slamseq/). Column oven temperature to use is 30 °C, with an injection volume of 100 µl, and flow rate of 500 µl/min. With these settings the run time is around 70 minutes. It is important to wash the column between runs. For additional details of standards, mobile phase solutions and isocratic gradient to use please refer to the [SLAMseq Explorer and Kinetics Kits User Guide](https://www.lexogen.com/docs/slamseq/) (p.16-17).
---
language: "en"
---
# Are there specific recommendations for demultiplexing QuantSeq FFPE using bcl2fastq?
Yes! When QuantSeq FFPE data is demultiplexed with bcl2fastq using default parameters, the output will not be usable because the UMI in Read 2 will contain only 'N'.
To correctly demultiplex, please use the following parameter in bcl2fastq:
It is --mask-short-adapter-reads arg (=22) smallest number of remaining bases (after masking bases below the minimum trimmed read length) below which whole read is masked
Per default, it masks reads shorter than 22 nucleotides.
For QuantSeq FFPE, it must be **set actively to 0** because the UMI is in each Read 2 (and only Read 2).
--mask-short-adapter-reads=0
---
language: "en"
---
# Are Unique Molecular Identifiers (UMIs) included in QuantSeq FFPE?
**Yes**!
A 12nt UMI sequence is included in the oligo(dT) primer and, therefore, located at the beginning of Read 2.
To read out the UMI sequence, a paired-end sequencing run is required (for more information, please see the following FAQs: [Can I use single read sequencing for QuantSeq FFPE?](https://faqs.lexogen.com/faq/can-i-use-single-read-sequencing-for-quantseq-ffpe.md) and [What sequencing read length and read depth are recommended for QuantSeq FFPE?](https://faqs.lexogen.com/faq/what-sequencing-read-length-and-read-depth-are-rec.md)).
---
language: "en"
---
# AVITI Loading Guidelines- CloudBreak Freestyle 2025
The loading guidelines provided below are for Lexogen libraries prepared using the **Cloudbreak Freestyle** workflows for sequencing on the Element Bioscience AVITI sequencing platform. These guidelines are based on the current experience of Lexogen. These guidelines are subject to change in the event of chemistry or AVITI Operating system (AOS) version updates made by Element Biosciences.
Loading amounts should be adjusted depending on average library sizes and in accordance with the recommendations provided by Element Biosciences for the version of the AOS in use. Please consult the applicable [++**CouldBreak Sequencing User Guide (MA-00058)**++](https://www.elementbiosciences.com/resources)when planning your run.
When sequencing Lexogen libraries for the first time on the AVITI, we recommend using the Individually Accessible Lanes (IAL) feature, and testing 2 different concentrations in 0.5 pM increments, starting at the average, or higher end of the provided loading ranges.
If you need to use the Adept workflow or UltraQ chemistry, or would like help to optimize your run conditions for specific lanemixes, please contact technical support at [++support@lexogen.com++](mailto:support@lexogen.com).
When contacting Lexogen technical support, please provide: *a copy of the linear lanemix size distribution* (trace file) showing average library/lanemix size, which library type(s) are included in the lanemix(es), the AVITI OS version, and sequencing kit to be used.
## Cloudbreak Freestyle
To determine loading concentration ranges, Lexogen libraries are classified as "***Third Party, PCR-Plus*** ". Unless otherwise indicated below, **2% PhiX** can be used as a routine spike-in. The table below provides both  tested and 👉 suggested loading concentration ranges, based on in-house and customer experience. Relevant AOS versions are indicated by superscript numbering.
**NOTE:** Loading concentrations for AVITI24 instruments may be higher than for standard AVITI runs. Please follow recommendations provided by Element Biosciences for the appropriate AVITI24 AOS version and sequencing chemistry/kit.
| **Library Type** | **Average Size Range** | **Loading Amount** | **Custom Primers Required?** | **Recommended Read Format** **(Seq. Kit)\*** | **Run Format** ^**3**^ **\[I1 (i7), I2 (i5), R1, R2\]** | **Additional Advanced Run Settings** ^**4**^ |
|--------------------------------|---------------------------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|----------------------------------------------------------------------------------------|----------------------------------------------|-------------------------------------------------------------------|----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
| CORALL RTM V2^2^ | 300 - 400 bp |  10 - 11 pM^v2.6, v3.3^ 👉 10 - 11 pM^v3.4^ | No | SR150 PE75 (2x75) | 12, 12, 151, 0 12, 12, 76, 76 | |
| CORALL RTL V2 | 300 - 450 bp 450 - 650 bp |  10 - 11 pM^v2.6, v3.3^  11.5 - 12.5 pM^v2.6^ 👉 11 - 12.5 pM^v3.4^ | No | SR150 (2x75) PE150 (2x150) | 12, 12, 151, 0 12, 12, 151, 151 | |
| CORALL FFPE^2^ | 250 - 400 bp | 👉 10 - 11 pM^v3.4^ | No | SR100-150 PE75 (2x75) | 12, 12, (101-151), 0 12, 12, 76, 76 | |
| QuantSeq FWD V2^2^ | 250 - 400 bp |  11 - 11.5 pM^v2.6^ 👉 9 - 11 pM^v3.4^ | No | SR100-150^1^ (2x75) | 12, 12, (101-151), 0 | |
| QuantSeq FWD V2^2^ | 400 - 500 bp |  12 - 13 pM^v2.6^ 👉 10 - 12 pM^v3.4^ | No | SR100-150^1^ (2x75) | 12, 12, (101-151), 0 | |
| QuantSeq FWD V2 - with UMIs^2^ | 300 - 450 bp |  11 - 12 pM^v2.6^ 👉 10 - 12 pM^v3.4^ **2% PhiX** for runs with \<= 20% of UMI libraries in total lanemix. -for advice on PhiX for runs that contain \>20% QuantSeq FWD-UMI libraries please contact [support@lexogen.com](mailto:support@lexogen.com) | No | SR75-150^1^ (2x75) | 12, 12, (76-151), 0 | |
| QuantSeq FWD FFPE with UDIs | 250 - 350 bp | 👉 9 - 11 pM^v3.4^ | No | SR75-100^1^ PE75-100/0-12 (2x75) | 12, 12, (76-101), 0 \[no UMI\] 12, 12, (76-101), 13 \[with UMI\] | |
| QuantSeq-Pool^2^ | 400 - 550 bp |  10 - 13 pM^v2.6^ 👉 10 - 13 pM^v3.3,v3.4^ | No | PE75-100/22 (2x75) | 12, 12, (76-101), 23 | |
| Luthor HD^2^ | 500 - 600 bp |  10 - 13 pM^v2.6^ 👉 10 - 13 pM^v3.3,v3.4^ | No | PE75-100/0-or-12 (2x75) | 12, 12, (76-101), 0 \[no UMI\] 12, 12, (76-101), 13 \[with UMI\] | |
| Luthor HD-Pool^2^ | 500 - 600 bp |  10 - 13 pM^v2.6^ 👉 10 - 13 pM^v3.3,v3.4^ | No | PE75-100/12-or-24 (2x75) | 12, 12, (76-101), 13 \[no UMI\] 12, 12, (76-101), 25 \[with UMI\] | |
| QuantSeq REV 3' mRNA Seq^2^ | 300 - 450 bp |  12 pM^v2.6,v3.3^ 👉 11 - 13 pM^v3.4^ **No PhiX!** | Yes - **CSP** 🔴 from QuantSeq REV V2 kit ^5^ \[use replacement workflow\] | SR100 (2x75) | 12, 12, 101, 0 | |
| QuantSeq REV 3' mRNA Seq^2^ | 300 - 450 bp | 👉 12 - 13 pM^v3.4^ **2% PhiX** - ***only if*** combined with other Lexogen libraries at \<= **25%** of lanemix.^6^ | No - ***only if*** combined with other Lexogen libraries at \<= **25%** of lanemix.^6^ | SR100 (2x75) | 12, 12, 101, 0 | |
| Lexogen Small RNA-Seq (052) | 143 bp (143 - 200 bp) | Use recommended loading concentration ranges provided by Element Biosciences, or contact [support@lexogen.com](mailto:support@lexogen.com) | No | SR75 (2x75) | 6, 0, 76, 0 |  short insert recipe^7^ |
| miRVEL Discovery | (200 bp) 150 - 300 bp | Use recommended loading concentration ranges provided by Element Biosciences, or contact [support@lexogen.com](mailto:support@lexogen.com) | No | SR50/72 (2x75) | 10, 10, 51, 0 \[no UMI\] 10, 10, 73, 0 \[with UMI\] |  short insert recipe^7^ |
| miRVEL Profiling | (143 bp) 143 - 200 bp | Use recommended loading concentration ranges provided by Element Biosciences, or contact [support@lexogen.com](mailto:support@lexogen.com) | No | SR50 (2x75) | 8, 8, 51, 0 |  short insert recipe^7^ |
\*The 2x300 cycle kits are not recommended for sequencing Lexogen RNA-Seq library types.
^1^ Although not recommended, QuantSeq FWD libraries can be sequenced in Paired End (PE i.e. PE75-100) mode, if required. In such cases, only Read 1 should be used for downstream QuantSeq data analysis. Note that you will see a quality drop for read 2, due to reading through the polyT-stretch at the start of the read. This may lead to a lower % Pass Filter (%PF) rate. See [this FAQ](https://faqs.lexogen.com/faq/can-i-use-paired-end-sequencing-for-quantseq-fwd-l.md) for more information.
^2^CORALL RTM and CORALL FFPE Libraries can also be sequenced using PE150 read formats. This does not impact %\>Q30 or %PF. For QuantSeq FWD/REV/Pool and Luthor HD/HD-Pool libraries, increasing the sequencing read length up to 150 bases (or the maximum allowed cycles when using a 2x75 kit and 12-24 cycle R2 lengths) is also possible. However, per base sequencing quality will typically decrease as read length increases, as more inserts will be fully covered and sequencing starts to read into the poly(A) stretch and adapter sequences.
^3^Provided run formats correspond to Lexogen's recommended sequencing formats for each library type. Read 2 sequencing formats for QuantSeq-Pool, QuantSeq FWD FFPE, Luthor HD and Luthor HD-Pool, are specified to enable correct sample demultiplexing and should ***not*** be extended. Longer read lengths for Read 1 for SR or PE formats may be possible depending on the sequencing kit used, and can be implemented at user's discretion.
^4^Use ***Standard*** ++Polony Density++ mode when sequencing new library types for the first time. After loading is optimized, or sufficient run quality and yield is established, ***High Density (HD)***mode can be used to further increase the run output. Effective use of HD Mode has been reported by Lexogen users.
Unless otherwise specified use of the ++PMG shift++ is not required. We recommend using ***default*** ++PMG settings++ (cycles 1-4), as Lexogen libraries retain sufficient nucleotide diversity at the start of read 1. If you wish to optimize, or have optimized PMG shifts for any of your runs, please get in touch with us at [support@lexogen.com](mailto:support@lexogen.com).
^5^When sequencing only QuantSeq REV libraries in a whole sequencing run you ++**must**++ use the **CSP** 🔴 provided in the QuantSeq REV V2 kit as a custom sequencing primer for **Read 1** . **IMPORTANT!** Use the **Replacement Custom Primer workflow** from Element Biosciences. **This workflow requires an additional reagent from Element Biosciences,** either: Custom Primer Set Read 1, Cloudbreak Freestyle (820-00038), or Custom Primer Set Cloudbreak Freestyle (820-00025). The **CSP** 🔴 ***should not*** be used, ***only*** if QuantSeq REV libraries are mixed with other Lexogen library types at \<=25% of the total lanemix. If required, additional aliquots of **CSP** 🔴 can be requested, please contact [support@lexogen.com](mailto:support@lexogen.com). See also [What is the CSP and how do I use it?](https://faqs.lexogen.com/faq/what-is-the-csp-and-how-do-i-use-it.md) for further information.
^6^Relative loading concentration for QuantSeq REV libraries included**at \<=25% of lanemixes** , comprising Lexogen libraries of similar average sizes. **NOTE:** Sequencing mixed library types in the same lane/run is inherently challenging, requires careful optimization for specific lanemix conditions, and therefore is generally not recommended. This advice is provided for QuantSeq REV as a guideline only. Customers choosing to run mixed lanemixes do so at their own risk. For further information see: [Can I pool Lexogen libraries with other library types in the same lanemix for sequencing?](https://faqs.lexogen.com/faq/can-i-pool-lexogen-libraries-with-other-library-ty.md).
^7^ Recommended if the aligned insert lengths are \<100 bp (i.e. for miRNA, piRNA, tRNA), corresponding to full-length average library sizes (insert + adapters) of \<250 bp. For further information on short insert recipe use cases and recommendations see [this article](https://go.elementbiosciences.com/sequencing-short-insert-libraries-cloudbreak-freestyle-tech-note-lt-00050) from Element Biosciences.
---
language: "en"
---
# BC1 Block Module for QuantSeq
The BC1 Block Module (RS-BC1 Block) for QuantSeq prevents the generation of library fragments from the abundant *BC1* transcripts that are present in mouse brain samples (*Mus musculus* , Mm). The module works by blocking the extension of BC1 inserts during second strand synthesis. The module is compatible with QuantSeq 3' mRNA-Seq Library Prep Kits for Illumina ([FWD V2, Cat. No. 191 - 196](https://www.lexogen.com/store/quantseq-3-mrna-seq-library-prep-kits-for-illumina/), and [REV V2, Cat. No. 225](https://www.lexogen.com/store/quantseq-3-mrna-seq-library-prep-kit-rev-for-illumina/)), and is intended for the preparation of libraries from mouse brain samples.
Download the [BC1 Block Module User Guide](https://www.lexogen.com/docs/quantseq-modules/).
Buy from our [Webstore](https://www.lexogen.com/store/bc1-block-module/).
---
language: "en"
---
# Can cells be fixed and then processed with LUTHOR HD?
We recommend that cells are fixed prior to isolation in order to preserve their transcriptomic state and recommend to work with cells showing a viability of at least 90%.
++Recommendations to assess viability:++
a. Trypan Blue staining
b. Dual Acridine Orange (AO)/Propidium Iodide (PI) staining. AO will stain live cells in green, while PI will stain dead cells in red.
**NOTE:**Trypan Blue stains debris, and if these are of similar size as cells, they can be wrongly counted as cells.
Therefore, when many debris are present, fluorescent staining AO/PI is preferred, since it will only stain cells.
Cell fixation guidelines have been validated internally and are outlined below:
***Buffers***
|----------------------------------------|-------------------------------------------------------------------|-------------------------|---------------------------------|
| **Buffer** | **Stock** | **Final concentration** | **To be added per Sample (μl)** |
| Fixation Buffer (FB) | 37% PFA 1x PBS pH7.4 | 4% # | 108.1 891.9 |
| Fixation/Permeabilization Buffer (FPB) | 37% PFA 1x PBS pH7.4 10% Triton X-100 | 4% # 0.1% | 108.1 881.9 10 |
| Quenching Buffer (QB) | 1M Tris-HCl pH8 1x PBS pH7.4 40 U/μl RNase Inhibitor | 200 mM # 0.16 U/ μl | 200 798 2 |
| Resuspension Buffer (RB) | H20, molecular biology grade 1x PBS pH7.4 40 U/μl RNase Inhibitor | # # 0.16 U/ μl | 500 498 2 |
***Specific Reagents***
|--------------------------|-------------------------------------------|--------------|
| **Vendor** | **Item** | **Cat. No.** |
| Sigma-Aldrich | DMSO (99.5 %) | D4540 |
| Thermo Fisher Scientific | Glycerol\* (99%, MBG) | J61059 |
| Thermo Fisher Scientific | PBS, pH 7.4 (no Ca, no Mg, no Phenol Red) | 10010-023 |
| Sigma-Aldrich | PFA (formaldehyde solution) | F1635 |
| Qiagen | RNase inhibitor, 40 U/μl | Y9240L |
*\*Mix 1:1 nuclease-free water with 99% Glycerol, filter through a 0.2 μm filter and store at room temperature in LoBind tubes*
***Fixation Temperature and Time***
* 1 h at 20ᵒC -- for samples which are to be processed immediately after fixation
* 12-24 h at 4ᵒC -- for samples which are to be stored
***Sample Fixation (tested with 1 M DU145 cells/ml)***
1. Pass cells through 40 μm strainer.
2. Centrifuge at 500 g for 3 min at 4-8ᵒC.
3. Remove the supernatant without disturbing the pellet.
4. Add 1 ml of **freshly prepared** Fixation Buffer (FB) or Fixation/Permeabilization Buffer (FPB).
***Note*** *: always prepare fresh FB*
5. Gently pipette-mix 5x.
6. Incubate for 12-24 h at 4ᵒC (for storage or shipment), or 1 h at 20ᵒC for immediate use.
7. Centrifuge at 500g for 3 min at 4-8ᵒC.
8. Remove the supernatant without disturbing the pellet.
9. Add 1 ml cold Quenching Buffer (QB) and gently resuspend cells. Keep on ice for 5 min.
***See storage guidelines*** **.**
10. Centrifuge at 500 g for 3 min at 4-8ᵒC.
11. Resuspend cells in 1 ml Resuspension Buffer (RB).
12. Pass cells through 40 μm strainer.
13. Count cells. Even when cells die after fixation, membrane may not be compromised, and may therefore prevent PI from entering the cell. Our recommendation is therefore to fix **and permeabilize** cells, ensuring PI staining of all dead cells. An efficient fixation protocol should give \>95% dead cells. Inefficient fixation will result into lower percentages of PI-stained cells (i.e., higher percentage of non-fluorescent cells).
14. After assessing viability, you can proceed by either:
1. Adding 2 µl of fixed cells (previously resuspended in RB, Step 11) to 3 µl of LUTHOR HD Cell Lysis Buffer (CLB), then proceed with the LUTHOR HD protocol as outlined in the [User Guide](https://www.lexogen.com/docs/luthor/) (Step 3, page 13) ++**OR**++
2. If sorting cells, we recommend following the protocol provided by the manufacturer of your cell sorter. Cells can be sorted directly into our Cell Lysis Buffer (CLB; please see Step 1, page 12 in the [User Guide](https://www.lexogen.com/docs/luthor/)). **IMPORTANT**: If submitting FACS-sorted samples to our Services department for LUTHOR Library Prep, please contact [support@lexogen.com](mailto:support@lexogen.com) for additional information.
***Fixed Sample Storage Guidelines***
* For short-term storage at 4ᵒC:
* Add 0.05 volume of DMSO to fixed sample in QB buffer.
* Store sample(s) at 4ᵒC max for 1 week.
* For long-term storage at -80ᵒC or shipment on dry ice, proceed as follow:
* Add 0.05 volume of DMSO to fixed sample in QB buffer (step 9, e.g. 50 µl DMSO to 1000 µl fixed sample). Gently pipette mix 5x.
* Add 50% Glycerol for a final concentration of 10%.
* Store at -80ᵒC for up to 6 months.
---
language: "en"
---
# Can cells be frozen and stored in the Cell Lysis Buffer?
**Yes**.
Pre-sorted cells and cell suspensions can be stored at -80°C in the Cell Lysis Buffer (CLB) provided with the LUTHOR HD kit.
**ATTENTION!** In this case, do not add the RNA Amplification Primer in the CLB and do not perform the cell lysis step! These will be done before proceeding with the library preparation when the samples will be thawed. For any questions, please contact our Tech Support team at [support@lexogen.com](mailto:support@lexogen.com).
---
language: "en"
---
# Can Globin Block be used with input amounts below 50 ng?
Input amounts down to 5 ng of total RNA from blood have been tested and can be used with adjustments to PCR cycle numbers.
For further information please contact [support@lexogen.com](mailto:support@lexogen.com).
---
language: "en"
---
# Can Globin Block Modules be used with low quality RNA?
**Yes.**
The Globin Block Modules can also be used to prepare QuantSeq libraries from low quality total RNA input from blood (RIN \<6). This will also result in a reduction of reads mapping to globin genes.
---
language: "en"
---
# Can I add blocking oligos to prevent the second strand synthesis of high abundant RNAs?
**Yes.**
Blocking oligos can be added during second strand synthesis together with the **TS** buffer. We recommend a final concentration of 10 -- 100 nM of blocking oligos during the second strand synthesis. Ideally, blocking oligos should be designed to bind close to the 3' end of the transcript(s) to block (this way exponential amplification of targeted highly abundant transcripts during the PCR is limited).
---
language: "en"
---
# Can I always replace QuantSeq FWD with QuantSeq-Pool?
**No!**
QuantSeq-Pool uses early pooling and thus equal read distribution in sequencing experiments requires normalization of the input RNA amount prior to starting library generation. This can be achieved best with high quality RNA (RIN \> 6) with at least 10 ng per sample.
The RNA input should also be homogenous in terms of integrity, purity, and quantity across all samples.
Pooling non homogeneous samples may result in unequal read share and hence, suboptimal read quality for some samples.
For further information please consult the Appendix information in the [QuantSeq-Pool Sample-Barcoded 3' mRNA-Seq User Guide](https://www.lexogen.com/docs/quantseq-pool/) and the following online FAQ: [What factors should I consider when switching from QuantSeq FWD to QuantSeq-Pool?](https://faqs.lexogen.com/faq/what-factors-should-i-consider-when-switching-from.md)
---
language: "en"
---
# Can I analyze my MGI data on Kangooroo?
**Yes!**
Lexogen libraries sequenced on MGI sequencing instruments can be analyzed on [Kangooroo](https://kangooroo.com/home).
For libraries including UMIs such as QuantSeq (FWD, FFPE and Pool), LUTHOR HD, CORALL and miRVEL Discovery, the read header of MGI FASTQ files must be first converted to Illumina format. To do so, you can use our MGI read converter tool available on our [Github](https://github.com/Lexogen-Tools/Fastq-Read-ID-Converter) webpage.

Figure 1: Conversion of MGI read header to Illumina read header format\*.
For any other Lexogen libraries (without UMIs), you can directly upload your MGI FASTQ files on the Kangooroo platform!
\**Source* .
---
language: "en"
---
# How can I analyze my QuantSeq data?
QuantSeq FWD, REV, FFPE and Pool kits come with a voucher code for free data analyses on our web-based platform [Kangooroo](https://kangooroo.com/home). Kangooroo offers tailored data analysis pipelines and specific configuration for each QuantSeq family product.
Please see the following FAQs for more information on how to analyze your QuantSeq Data:
* [How can I analyze my QuantSeq FWD V2 Data?](https://faqs.lexogen.com/faq/can-i-analyze-my-quantseq-with-udi-v2-data-using-t.md)
* [How can I analyze my QuantSeq REV V2 Data?](https://faqs.lexogen.com/faq/how-can-i-analyze-my-quantseq-rev-v2-data.md)
* [How can I analyze my QuantSeq FFPE data?](https://faqs.lexogen.com/faq/how-can-i-analyze-my-quantseq-ffpe-data.md)
* [How can I analyze my QuantSeq Pool data?](https://faqs.lexogen.com/faq/how-do-i-analyze-my-quantseq-pool-data-can-i-use-t.md)
The voucher code covers the analysis of the same number of samples as the reactions in the kit (i.e., for a 24 reaction kits, you can analyze 24 samples), including differential expression analysis.
**ATTENTION!**Codes are valid 2 years after the purchase of the kit.
For additional information about Kangooroo, please visit our website [Lexogen - Kangooroo](https://www.lexogen.com/kangooroo-ngs-data-analysis/) and check our [Kangooroo Data Analysis](https://faqs.lexogen.com/faq/kangooroo-data-analysis.md)FAQs.
---
language: "en"
---
# How can I analyze my QuantSeq with UDI V2 data?
Our QuantSeq FWD V2 kit comes with a voucher code to access free data analysis on our web-based platform [Kangooroo](https://kangooroo.com/home).
Kangooroo offers tailored data analysis pipelines optimized for QuantSeq FWD data with or without UMIs!
For more information, please visit our website [Lexogen - Kangooroo](https://www.lexogen.com/kangooroo-ngs-data-analysis/) and our online [Kangooroo Data Analysis](https://faqs.lexogen.com/faq/kangooroo-data-analysis.md)FAQs!
If additional voucher codes are needed, please contact us at [sales@lexogen.com](mailto:sales@lexogen.com).
**NOTE**: Our QuantSeq FWD pipelines utilize single-read data only. Please, only upload Read 1 FASTQ files.
If you prefer to analyze your QuantSeq FWD data on your own, as reference you can find below the general workflow with key steps to successfully analysis your QuantSeq data!
++Key steps of the general workflow to use to analyze QuantSeq FWD data:++
| **QuantSeq FWD** | **QuantSeq FWD - UMI** |
|----------------------------------|----------------------------------|
| - | UMI extraction |
| Trimming | Trimming |
| Mapping | Mapping |
| - | UMI collapsing |
| Gene Read counting | Gene Read counting |
| Differential Expression Analysis | Differential Expression Analysis |
---
language: "en"
---
# Can I buy the Elution Buffer (EB) separately?
The Elution Buffer (EB) is included in all library preparation kits, as well as the Purification Module (Cat. No. 022) and RiboCop rRNA Depletion Kits (Cat. No. 125-127, 144-145, 190, 237, 241).
The Elution Buffer is not sold separately.
If required EB can be substituted by a solution of 10 mM TRIS, pH 8.0.
---
language: "en"
---
# Can I choose the sequencing depth and read length?
Please let us know if you have a preferred sequencing format (single-read (SR) or paired-end (PE)), or required sequencing depth. Sequencing mode and depth depends on library type and project requirements and will be discussed before sample submission.
---
language: "en"
---
# Can I expect changes in the expression of other transcripts when depleting BC1?
Users may see changes in absolute abundance of several genes, but this will not negatively affect the ability to detect differential expression between experimental groups.
---
language: "en"
---
# Can I extract DNA with the SPLIT Kit?
**No**.
The kit is for RNA extraction only. However, since SPLIT is based on acidic phenol-chloroform extraction, DNA and proteins will be located in the lower organic phase. You can attempt to recover and purify DNA from the organic and inter-phases. In order to do so, however, you should omit the use of the Phase-Lock tubes. For more information, please contact [support@lexogen.com](mailto:support@lexogen.com).
---
language: "en"
---
# Can I extract the RNA downstream of TraPR with methods other than phenol-chloroform, e.g. with TRIzol or silica spin-columns?
**Yes.**
In principle, any other method for RNA extraction can be used in conjunction with TraPR.
---
language: "en"
---
# Can I get script files for QuantSeq automation?
Our QuantSeq library prep protocols have been automated on most major liquid handers (please see this [++FAQ++](https://faqs.lexogen.com/faq/on-which-liquid-handler-is-the-quantseq-protocol-a.md)).
For automation scripts, we invite you to contact the FAS of the liquid handler manufacturer to obtain the latest and most appropriate script for our protocol on your instrument. Scripts may vary based on the liquid handler used, deck setup, software versions, consumables, and manual interventions. Therefore, for setting up automation of our protocols, we prefer to direct our customers ++to the specific FAS of the platform used (or to be used).++
**NOTE:** Internally, we use the Biomek i7 platform for automation. Connect us with your local FAS and we can provide the latest script file and work together to obtain the optimal program script for your particular instrument.
++Please find below our general recommendations for automation settings:++
* As mentioned, contact the FAS of the liquid handler to check the compatibility of your instrument with the latest version of the automation script protocol.
* Perform a dry run to ensure there are no errors or incompatibilities.
* Perform a dummy run for volume checks after program installation. We recommend wet runs before using real samples to ensure reaction volumes are correct with the dummy reagents you already have.We recommend these be used before real samples are run to ensure reaction volumes are correct.
* Purification module for automation optimization are not included in the dummy kit. We recommend the purification steps be optimized using real reagents due to the critical nature of these steps because these buffers are hard to mimic correctly.
* Perform a test run for a small subset of sample using a reference RNA. It is recommend to run a manual prep in parallel to compare results downstream.
**NOTE:**Automation scripts are typically provided for the full library prep protocol. Automating only the post-PCR purification can also be achieved by modifying an existing Post-PCR SPRI bead purification program. Please ensure the double bind steps are included.
**IMPORTANT:** Lexogen is not an automation company, and although we're happy to support our customers as much as we can (e.g., looking at the results to help the troubleshooting and providing our input), any script modifications and the initial steps of installations should be performed by the platform provider.
---
language: "en"
---
# Can I install the automated protocol myself?
The protocol script files that can be provided have been developed for the softwares and instrument types specified by each manufacturer. However, software version compatibility, and deck compatibility should always be checked first by the manufacturer of your instrument to ensure that the script will run correctly. It is usual that some optimization is required.
We recommend the following process when adopting automation of any of our library prep protocols:
1. Contact the Field Application Specialist (FAS) or manufacturer of your liquid handler and ask them to check the compatibility of your instrument with the latest version of the automation script protocol.
2. After installing the program, perform a dry run to ensure there are no errors or incompatibilities.
3. Perform a dummy run using dummy reagents and check volume accuracy. We strongly recommend performing a dummy run using real purification reagents.
4. Perform a test run for a small number of replicates, using reference RNA (e.g., Universal Human Reference RNA, Agilent Technologies, Cat. No. 740000).
We can supply dummy reagents for optimizing liquid handling steps (Cat. No. 019.384, shipping charges apply).
Additional Magnetic Bead Purification Modules can be purchased for this purpose (Cat. No. 022, please enquire with your distributor or Account Manager for pricing).
Contact our Tech Support Team ([support@lexogen.com](mailto:support@lexogen.com)) to order dummy reagents, or for feedback on your automation implementation or library preparation results.
---
language: "en"
---
# Can I merge my FASTQ files on Kangooroo?
**Yes!**
To merge FASTQ files, please use the sample creation option (click on icon "Sample Create") in the project tab and:
* Define the name of the sample
* Select the FASTQ files for Reads (Read 1, and Read 2 if necessary) that need to be merged
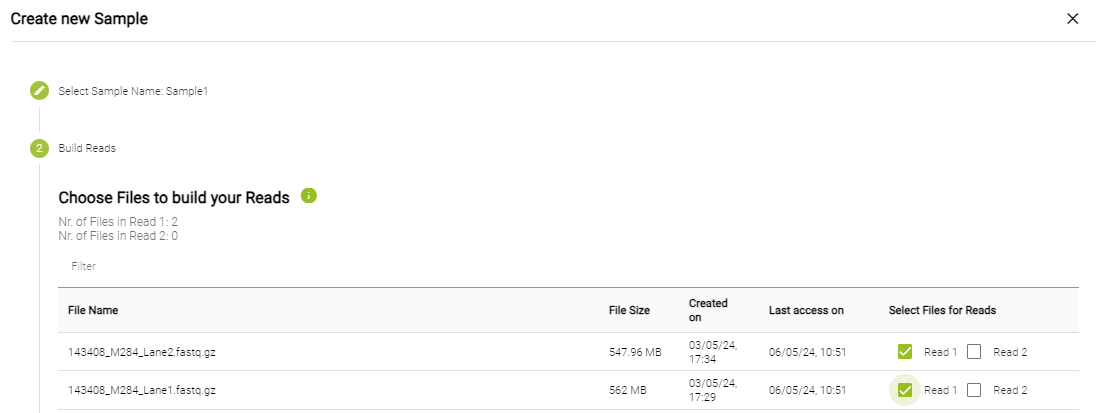
* Enter the sample condition, if required
* Click on "create sample"
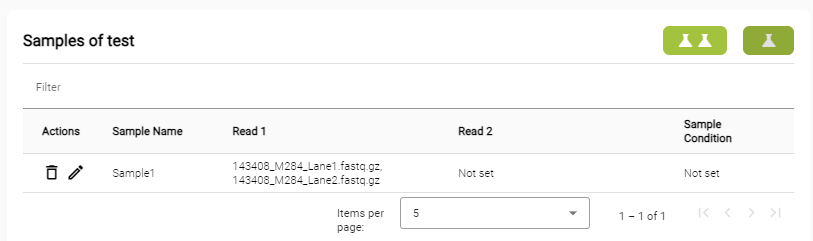
The newly created sample will appear in the *Sample* widget. The sample name, the FASTQ files for Reads and the sample condition corresponding to the created sample will be displayed. Sample editing after sample creation is possible by clicking on the ´´pencil´´ icon.
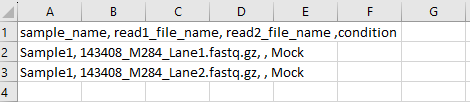
When using the bulk sample creation option (i.e., when clicking on the icon "Bulk-create New Samples"), enter the same sample name in the sample file (column Sample_name) for all the FASTQ files that need to be merged, and ONLY for the FASTQ files to merge.
Do not use the same sample name for FASTQ files that should not be merged and which are to be analyzed as separate samples.
Please watch our tutorial video on how to create bulk samples and merge FASTQ files [here](https://www.youtube.com/watch?v=q9XwmxB227s&t=10s).
---
language: "en"
---
# Can I pool Lexogen libraries with other library types in the same lanemix for sequencing?
We do not recommend multiplexing Lexogen libraries with libraries from other vendors in the same sequencing lane. Though this is possible in principle, specific optimization of index combinations, library pooling conditions, and loading amounts will be required for optimal performance on individual instruments.
Sequencing complex pools that include different library types at different lane shares may have unpredictable effects on sequencing run metrics, read quality, read outputs, and/or demultiplexing performance. Lexogen assumes no responsibility for the altered performance of Lexogen libraries sequenced in combination with external library types in the same lane (or run).
Due to size differences, libraries prepared with the Lexogen Small RNA-Seq Library Prep Kit (or any other small RNA library prep kit) should not be sequenced together with QuantSeq, CORALL, or LUTHOR HD libraries.
Please refer to the sequencing guidelines for each library type (library adapter details, loading amounts to use, use of custom sequencing primers, etc.), which are provided in our Library Prep Kit User Guides, and online Frequently Asked Questions (FAQs).
---
language: "en"
---
# Can I reamplify my libraries using the PCR and Reamplification Add-on Kit?
If your library yields are extremely low and insufficient for pooling, reamplification can be performed using the [PCR Add-on and Reamplification Kit V2](https://www.lexogen.com/store/pcr-add-on-and-reamp-v2/)(Cat. No. 208.96).
---
language: "en"
---
# Can I receive the remaining sample (RNA, cells, tissues) after it has been submitted for services?
Yes, we are happy to return any remaining material to you. Please inform us about your wish to receive the leftover material (if any) before the project starts or within 3 months after the project is completed. The shipment for the return of material will be charged.
---
language: "en"
---
# Can I run the protocol without thermomixer?
If you do not have a thermomixer available, you can utilize a thermocycler or heat block without agitation.
---
language: "en"
---
# Can I sequence my miRVEL Small RNA-Seq libraries if the concentration is lower than the recommended 4 nM?
**Yes.**
It is possible if final library QC indicates that the library is good quality. You can sequence the library at a concentration of 2 nM or at the maximum available amount for that library, either individually or in multiplex with other samples. We recommend using comparable concentrations for all libraries being multiplexed.
---
language: "en"
---
# Can I ship samples from any country?
Lexogen is open to providing Services for customers from any country, subject to the [General Terms and Conditions of Sales](https://www.lexogen.com/terms-and-conditions/).
---
language: "en"
---
# Can I split my Kangooroo voucher into multiple vouchers?
**Yes!**
To split your voucher(s), please contact [support@lexogen.com](mailto:support@lexogen.com).
**IMPORTANT:****Do not redeem your voucher code to your Kangooroo account**!
---
language: "en"
---
# Can I store SIRV dilutions for further use?
**No.**
SIRV dilutions should be considered as single-use only and should not be freeze-thawed.
We do not recommend storing SIRV dilutions as the risk of degradation and absorption to the tube increases over time, even with optimal storage at/or below -80 degrees Celsius.
For this reason we recommend to aliquot the SIRV stock solutions upon first use into 1 ul volumes, and store at/or below -80 degrees until needed.
Best practice is to prepare and use SIRV dilutions immediately before use, keeping the stock and dilutions continuously on ice, and using careful RNase-free handling technique, to minimize the risk of degradation.
Please see the [SIRV User Guides](https://www.lexogen.com/docs/sirvs-mixes/) for specific guidelines for handling SIRV dilutions.
---
language: "en"
---
# Can I use custom primers for reverse transcription or PCR?
**Yes.**
The Reverse Transcription, PCR Forward, and PCR Reverse Primers are added separately in the TeloPrime V2 protocol and can easily be exchanged. For details of custom primer use, please see Appendix D of the TeloPrime V2 [User Guide](https://www.lexogen.com/docs/teloprime/).
---
language: "en"
---
# Can I use low quality RNA as input for TeloPrime Full-Length cDNA Amplification?
It is possible, but it is not recommended. We recommend using the highest quality RNA available as input for TeloPrime cDNA generation. Lower quality RNA (RIN \< 8) can also be used as input. However, as RNA integrity decreases the proportion of transcripts with an intact 5' cap is reduced.
TeloPrime can still generate full-length cDNA from remaining intact capped and polyadenylated mRNAs present in low quality total RNA samples, though the maximum length of the amplified cDNA may be reduced compared to cDNA prepared from higher quality inputs.
When using lower quality RNA as input, the Optimal Endpoint PCR cycle number (OEP) should be determined using the qPCR assay (see [this relevant FAQ](https://faqs.lexogen.com/faq/how-is-the-cycle-number-of-the-endpoint-pcr-determ.md), and Appendix B of the TeloPrime V2 [User Guide](https://www.lexogen.com/docs/teloprime/)).
---
language: "en"
---
# Can I use other fluorophores instead of SYBR Green?
The performance of the PCR Add-on and Reamplification Kit V2 was extensively validated with the SYBR Green I nucleic acid dyes listed in the User Guide ([Sigma Aldrich, S9430](https://www.sigmaaldrich.com/US/en/product/sial/s9430); [ThermoFisher S7563](https://www.thermofisher.com/order/catalog/product/S7563)).
We do not recommend the use of qPCR master mixes or alternative fluorophores (e.g., EvaGreen) as their performance can vary and influence calculation of the endpoint cycle number. If other fluorophores are utilized, the endpoint cycle numbers may need to be calculated differently and verified by Endpoint PCR testing prior the library amplification.
---
language: "en"
---
# Can I use paired-end sequencing for QuantSeq FWD libraries?
Paired-end (PE) sequencing is typically not recommended for QuantSeq FWD (Cat. No. 191 - 196), as the quality of Read 2 is very low due to the poly(T) stretch at the beginning of Read 2.
Nevertheless, QuantSeq FWD libraries can be sequenced in PE mode (i.e., 150bp) but in this case, we recommend discarding Read 2 data and proceeding with Read 1 data only for downstream data analysis (i.e., use only Read 1 for trimming, alignment, read counting, and downstream analyses).
---
language: "en"
---
# Can I use paired-end sequencing for QuantSeq REV libraries?
**Yes!**
You can perform Paired-end (PE) sequencing using QuantSeq REV. Please note QuantSeq REV requires a Custom Sequencing Primer (CSP) for Read 1 sequencing in order to generate reads that begin at the exact 3' end of the transcript.
For more information on how to sequence your QuantSeq REV libraries, please see this [++FAQ++](https://faqs.lexogen.com/faq/what-is-the-csp-and-how-do-i-use-it.md).
---
language: "en"
---
# Can I use QuantSeq-Flex with the QuantSeq REV 2 Version?
QuantSeq-Flex Second Strand Synthesis Module V2 ( Cat. No. 028) can be used in combination with QuantSeq REV 2 (Cat. No. 225). Since first strand synthesis introduces a P5 adaptor, a P7 adaptor needs to be added to the second strand custom oligo as follow:
Partial P7 adapter -- (Optional) UMI - Targeted Sequence:
5'GTTCAGACGTGTGCTCTTCCGATCT - (NNNNNN(NN)) - Target Sequence (= RNA-sequence)3'
Here the target sequence has to be the RNA-sequence in question.
**NOTE:** A longer UMI is recommended, up to 12nt UMI: (NNNNNN(NN(NN)(NN)))
**NOTE:** If UMIs are added during second strand synthesis, asymmetric PE sequencing will need to be performed to read out the UMI.
[Next Page](https://faqs.lexogen.com/llms-full.txt/1)